
A candidate match score looks like a simple number, 78%, 92%, a green checkmark next to a name, but the process behind that number involves comparing dozens of individual data points across several dimensions, not running a single keyword count. This article focuses specifically on that comparison and scoring layer: what actually gets compared, how a system handles two resumes that describe similar experience in completely different language, and what a score is actually telling a recruiter versus what it isn’t.
This is narrower than a general explanation of AI resume screening. Screening covers the full pipeline, from parsing a document to a recruiter’s final review. Matching is the specific step inside that pipeline where a candidate’s profile gets compared against a role’s requirements, and it’s worth understanding on its own, since it’s the step most likely to be misread as more precise than it actually is.
Key Takeaways
Matching is a comparison step, not the whole screening process. It sits between parsing a resume and producing a ranked shortlist, and it’s worth understanding separately from the broader pipeline.
Modern matching systems compare meaning, not just words. Semantic matching techniques can recognize that “wrote SQL queries in Snowflake” and “SQL experience” describe the same underlying skill, though how reliably varies by system.
A score is a weighted composite, not a single measurement. Technical skills, experience relevance, education, and other dimensions typically get scored separately, then combined, which means two very different resumes can land on a similar overall number.
A high match score describes fit against stated criteria, not job performance. It should inform where a recruiter looks first, not replace the recruiter’s evaluation.
AI Resume Screening vs. AI Candidate Matching vs. Candidate Scoring
These three terms get used interchangeably in most vendor marketing, which creates real confusion about what’s actually being evaluated at each step.
| Term | What It Refers To | Where It Sits in the Process |
| AI resume screening | The overall process of parsing, evaluating, and filtering an applicant pool | The umbrella term for the whole pipeline |
| AI candidate matching | The specific step where a candidate’s data is compared against job requirements | One stage within screening, focused on comparison |
| Candidate scoring | The numerical output that matching produces | The result of matching, used to rank candidates |
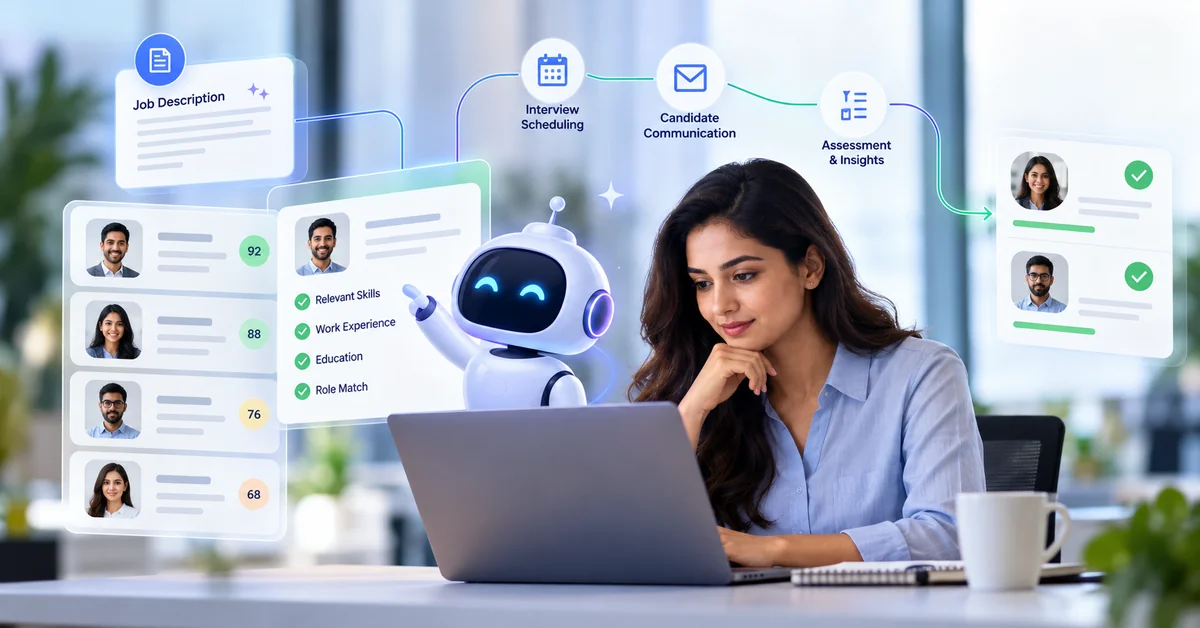
In practice: screening is the process, matching is the mechanism, and scoring is the output. A conversation about “improving our AI screening” is usually really a conversation about improving the matching logic or how the resulting score gets used, and being specific about which one is under discussion tends to produce a more useful conversation.
What Information Does AI Candidate Matching Actually Compare?
Matching compares structured and semi-structured data extracted from a resume, skills, job titles, employment dates, education, and sometimes certifications or described accomplishments, against the same categories extracted from a job description. The comparison typically happens dimension by dimension rather than as one undifferentiated block of text, which is what allows a system to weigh, say, technical skills separately from years of experience.
How AI Understands Job Requirements
Before any comparison happens, the system has to turn a job description into something comparable: a structured set of required and preferred criteria, each with an implicit or explicit level of importance. A well-written job description that clearly separates “required” from “nice to have” gives the system a meaningfully better foundation than a bloated list where every line reads with equal weight. This is also where the limitations described later in this article usually start: a system can only extract structure that’s actually present in the text it’s given.
How AI Identifies Relevant Skills
Skill identification happens two ways. Explicit skills are ones a candidate lists directly, “SQL,” “Project Management,” “Adobe Photoshop.” Inferred skills are ones a system extracts from context, recognizing that someone who “led a cross-functional team of eight through a six-month product launch” has demonstrated project management ability without using that exact phrase. Inferred skill detection is considerably harder to get right than explicit keyword matching, and it’s the single biggest differentiator in quality between a basic keyword tool and a more sophisticated matching system.
How AI Handles Synonyms and Transferable Skills
Modern matching systems increasingly rely on a technique called semantic embedding: converting both the job requirements and the candidate’s resume into numerical representations that capture meaning rather than exact wording, then measuring how close those representations are to each other. This is what allows a system to recognize that “client-facing communication” and “stakeholder management” describe overlapping skills, or that experience with one BI tool suggests transferable ability with a similar one, without an exact keyword match. It’s a meaningfully more capable approach than simple keyword or Boolean matching, though it isn’t infallible, and how well it performs varies significantly across vendors and implementations.
How Different Candidate Attributes Get Weighted
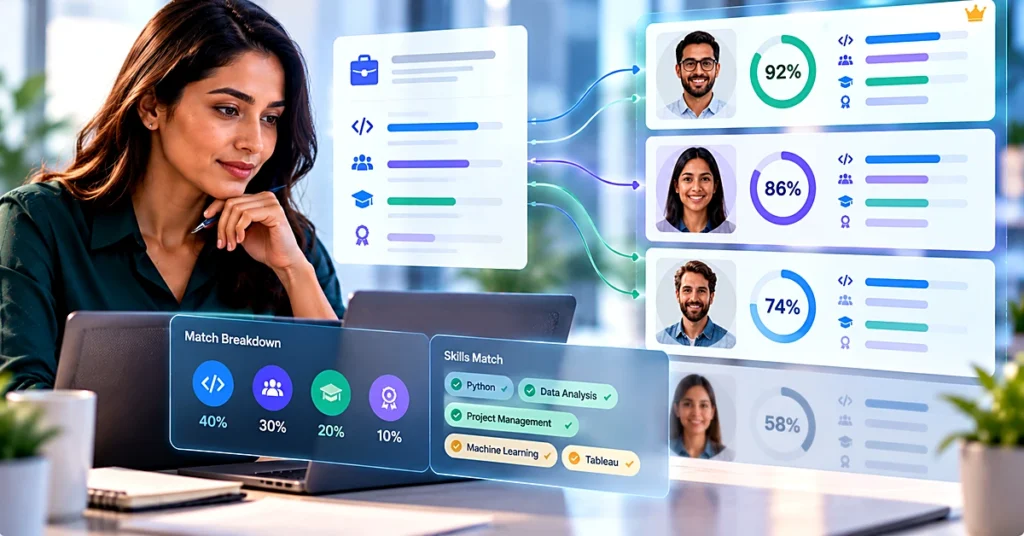
A match score is rarely one calculation. It’s typically several sub-scores, skills match, experience relevance, education, sometimes location or availability, combined using a weighting scheme that determines how much each dimension counts toward the final number. A role where hands-on technical skill matters most might weight skills match at 50% of the total score; a client-facing role might weight communication-related signals more heavily. Getting this weighting wrong, treating years of experience as equally important as core skill match for a role where skill matters far more, is one of the more common and least visible ways a matching system produces misleading results.
A Worked Example: Two Candidates, Same Job, Different Scores
Consider a Senior Data Analyst opening requiring SQL, familiarity with a BI or dashboarding tool, five or more years of analytics experience, a bachelor’s degree, and the ability to communicate findings to non-technical stakeholders.
Candidate A has a resume that mirrors the job description closely: five years as a Data Analyst, SQL and Python listed explicitly, Power BI dashboard experience named directly, and a bachelor’s degree in Statistics. Candidate B has four years as a Marketing Analytics Specialist, describes writing “complex queries to extract campaign performance data from Snowflake,” built “interactive Tableau dashboards for leadership,” and presented “monthly performance reviews to VP-level stakeholders,” with a bachelor’s degree in Marketing and a statistics minor.
A simple keyword matcher would likely rank Candidate A well ahead of Candidate B, since B’s resume never uses the literal words “SQL” or “five years,” and lists a different degree field entirely. A multi-dimensional semantic system reads the underlying signal differently:
| Dimension | What It Measures | Candidate A | Candidate B |
| Technical skills match | SQL, Python, BI/dashboard tools | 95% | 80% |
| Experience relevance | Years and closeness of role match | 100% | 80% |
| Education match | Degree field and level | 90% | 70% |
| Communication/stakeholder experience | Evidence of presenting to or working with stakeholders | 60% | 95% |
| Weighted overall score | 86% | 81% |
Candidate A scores higher overall in this illustration, but Candidate B scores competitively despite a resume that would have been filtered out or ranked much lower by a keyword-only system, because the underlying skills and experience are genuinely there, just described in different language. This is exactly the scenario semantic matching is designed to catch, and exactly the scenario a rigid keyword system misses by default.
What a Match Score Actually Means (and Doesn’t)
A match score describes how closely a candidate’s stated profile aligns with the stated requirements of a role, weighted according to whatever scheme the system was configured with. It does not measure job performance, cultural fit, interview ability, or the accuracy of anything the candidate wrote on their resume. Two candidates with identical scores can be meaningfully different hires, and a lower-scored candidate can outperform a higher-scored one, because a score is a similarity measurement against text, not a prediction of how someone will actually do the job.
Limitations of AI Candidate Matching
Incomplete job descriptions. A matching system can only weigh what’s in the requirements it’s given. A job description missing a genuinely important requirement, or padded with requirements that don’t actually matter, produces a score that’s confidently wrong in either direction.
Incorrect weighting. A system configured to weight years of experience heavily for a role where recent, relevant skill matters more will systematically favor tenure over actual fit.
Missing resume information. A skill demonstrated on the job but never written down doesn’t exist to the matching system, regardless of how real it is.
Keyword and phrasing gaps. Even semantic systems perform better on common phrasing patterns than on unusual ones; a candidate who describes their experience in genuinely idiosyncratic language may still score lower than the underlying substance warrants.
Non-traditional candidates and career changers. A candidate whose relevant experience comes from a different industry or an unconventional path requires the system to draw connections across a bigger semantic gap, which is harder to do reliably than matching within a single, well-represented career track.
Historical bias. A system trained or tuned using data from past hiring decisions can encode the patterns in that data, including patterns that reflect prior bias rather than genuine job-relevant differences.
False confidence in AI scores. A precise-looking number, 87% versus 82%, implies a level of certainty the underlying comparison doesn’t actually have. Small differences in phrasing can move a score by several points without reflecting any real difference in the candidate’s ability.
Why a High Match Score Shouldn’t Be an Automatic Hiring Decision
A match score is genuinely useful for one thing: helping a recruiter decide where to look first in a large applicant pool. It’s a starting point for prioritization, built on a comparison between two pieces of text, not a validated prediction of job performance. Treating a score threshold as an automatic pass or fail replaces a recruiter’s judgment with a number that was never designed to carry that weight on its own.
A matching system that shows its work, why a candidate scored the way they did, dimension by dimension, rather than a single opaque number, gives a recruiter something to actually evaluate rather than just trust. That transparency is the specific design principle behind SmoothHiring’s smart candidate matching, which surfaces the reasoning behind a score rather than presenting it as a final verdict.
Frequently Asked Questions
How does AI match candidates to jobs?
How does AI match candidates to jobs?
AI candidate matching compares structured data extracted from a resume, skills, experience, education, against the requirements extracted from a job description, using techniques ranging from keyword matching to semantic comparison that can recognize related concepts described in different language.
How does AI score a resume?
Most systems generate several sub-scores across dimensions like skill match, experience relevance, and education, then combine them using a weighting scheme into a single overall score used to rank candidates.
What is a candidate match score?
A candidate match score is a numerical representation of how closely a candidate’s profile aligns with a role’s stated requirements. It reflects textual and data similarity, not a validated measure of future job performance.
Is AI candidate matching better than keyword matching?
Semantic matching generally identifies more relevant candidates than pure keyword matching, since it can recognize related skills described in different terms. It isn’t infallible, and its accuracy depends heavily on the quality of the job requirements and the sophistication of the underlying matching technique.
Can AI understand transferable skills?
Modern semantic matching systems can identify some transferable skills by recognizing related concepts across different phrasing, but this is harder across a bigger gap, such as a career changer moving between unrelated industries, than within a closely related field.
Does a high match score mean a candidate should be hired?
No. A high match score indicates strong alignment with stated requirements as written, not a guarantee of job performance, cultural fit, or interview success. It should guide where a recruiter looks first, not replace their evaluation.
Conclusion
AI candidate matching does something genuinely useful: it turns an unmanageable pile of resumes into a ranked, comparable list based on real similarity between what a role needs and what a candidate offers. What it doesn’t do is remove the judgment call at the end. A weighted score is a strong starting point built on the quality of the job requirements, the sophistication of the matching technique, and the completeness of what a candidate chose to write down, and all three of those can be wrong in ways the score itself won’t reveal.
The quality of matching depends heavily on the platform underneath it. Worth understanding how a modern applicant tracking system structures job requirements and candidate data before comparing them, since that foundation shapes everything the matching layer is able to do well.